GitHubPyPI
FunASR
#31 of 50 in the AI Agent Index ↓ Download poster
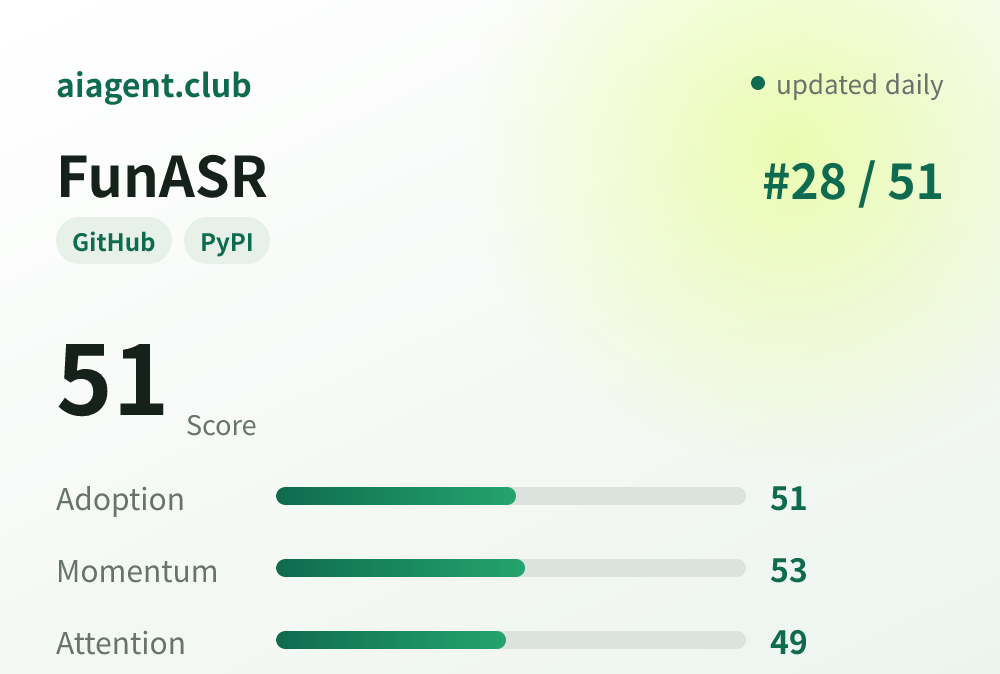
46 Score
Observed adoptionCurrent · 2026-10-27 44
MomentumCurrent · 2026-10-26 48
AttentionCurrent · 2026-10-26 46
Signal confidence Based on how many independent score dimensions currently have data.
High3/3 · 2 source types
About
Industrial speech recognition. 170x faster than Whisper. 50+ languages.
No local setup? Open the Colab quickstart to transcribe a public sample or upload your own audio in a browser.
Flagship model — Fun-ASR-Nano (LLM-ASR, 31 languages; the default recommendation, needs a GPU):
On CPU (or for multilingual + emotion in one pass), use SenseVoice — which also returns speaker diarization and timestamps:
Output — structured text with speaker labels, timestamps, and punctuation:
That's it. One model, one call — VAD segmentation, speech recognition, punctuation, speaker diarization all happen automatically.
At scale, accelerate Fun-ASR-Nano with vLLM (batch processing):
Deploy as API…
Across sources
272.5k Downloads / month
- Downloads / month 272.5k
- Downloads / week 96.9k
- Downloads / day 14.5k
20.8k Stars
- Stars 20.8k
- Forks 2.1k
- Commits 6.0k
- Releases 65